


Advertisement
Advertisement
Deep Cogito, a relatively obscure AI research startup located in San Francisco and established by former Googlers, has launched four new open-ish large language models (LLMs) that endeavor to achieve what few others do: Enhancing reasoning capabilities over time and independently improving in this aspect.
The models, introduced as part of Cogito’s v2 series, range from 70 billion to 671 billion parameters and are accessible to AI developers and enterprises under a combination of restricted and fully open licensing terms. They include:
Cogito v2-70B (Dense)
Cogito v2-109B (Mixture-of-experts)
Cogito v2-405B (Dense)
Cogito v2-671B (MoE)
Dense and MoE models cater to different requirements. Dense 70B and 405B variants activate all parameters on each forward pass, which makes them more predictable and easier to deploy across diverse hardware.
These models are optimal for low-latency applications, fine-tuning, and environments with limited GPU capacity. MoE models, such as the 109B and 671B versions, employ a sparse routing mechanism that activates only a few specialized “expert” subnetworks at a time, allowing for much larger overall model sizes without a corresponding increase in computational cost.
AI Scaling Hits Its Limits
Power caps, rising token costs, and inference delays are reshaping enterprise AI. Join our exclusive salon to discover how top teams are:
Turning energy into a strategic advantage
Architecting efficient inference for real throughput gains
Unlocking competitive ROI with sustainable AI systems
Secure your spot to stay ahead: https://bit.ly/4mwGngO
These models are particularly suitable for high-performance inference tasks, research into complex reasoning, or providing frontier-level accuracy at a reduced runtime cost. Within Cogito v2, the 671B MoE model stands out as the flagship, utilizing its scale and routing efficiency to match or surpass leading open models on benchmarks — all while employing significantly shorter reasoning chains.
The models are currently available on Hugging Face for download and enterprise use, as well as on Unsloth for local usage. For those unable to host the model inferences on their own hardware, application programming interfaces (APIs) are available from Together AI, Baseten, and RunPod.
Additionally, there is a quantized “8-bit floating point (FP8)” version of the 671B model, which reduces the bit size used for the model's parameters from 16-bits to 8-bits, allowing users to run extensive models faster, more cost-effectively, and on more accessible hardware — sometimes with only a minimal impact on performance (95 to 99%). Nonetheless, this can slightly affect model accuracy, particularly for tasks requiring precise calculations (such as some math or reasoning problems).
All four Cogito v2 models are conceived as hybrid reasoning systems: They can provide immediate responses to queries or, when necessary, reflect internally before answering.
Importantly, this reflection is not just a runtime feature — it is embedded in the training process itself.
These models are trained to internalize their own reasoning processes. This means that the paths they take to reach conclusions — their mental steps, in a manner of speaking — are integrated back into the models’ weights.
Over time, they learn which reasoning paths are significant and which are not.
According to a blog post by Deep Cogito, the researchers “discourage the model from ‘wandering more’ to arrive at the answer, and instead foster a stronger intuition for the appropriate search trajectory in the reasoning process.”
As a result, Deep Cogito asserts, there is faster, more efficient reasoning and a general enhancement in performance, even in what is referred to as “standard” mode.
Self-improving AI
While many in the AI community are only now learning about the company, Deep Cogito has been quietly developing its technology for over a year.
The company emerged from stealth in April 2025 with a series of open-source models trained on Meta’s Llama 3.2. These initial releases demonstrated promising results. This followed a $13 million seed funding round that concluded in November 2024, led by Benchmark, with Benchmark’s Eric Vishria joining the company’s board.
As VentureBeat previously reported, the smallest Cogito v1 models (3B and 8B) outperformed Llama 3 counterparts across several benchmarks — sometimes significantly.
Deep Cogito CEO and co-founder Drishan Arora — formerly a lead LLM engineer at Google — described the company’s long-term objective as creating models that can reason and improve with each iteration, much like how AlphaGo enhanced its strategy through self-play.
Deep Cogito’s primary method, iterated distillation and amplification (IDA), replaces hand-written prompts or static teachers with the model’s own evolving insights.
What is ‘machine intuition’?
With Cogito v2, the team expanded this approach to a much larger scale. The central concept is straightforward: Reasoning should not merely be a tool for inference; it should be integrated into the model’s core intelligence.
Consequently, the company implemented a system where the model executes reasoning chains during training and is then trained on its intermediate thoughts.
This process yields tangible improvements, according to internal benchmarks. The flagship 671B MoE model surpasses DeepSeek R1 in reasoning tasks, matching or exceeding its latest 0528 model while utilizing 60% shorter reasoning chains.
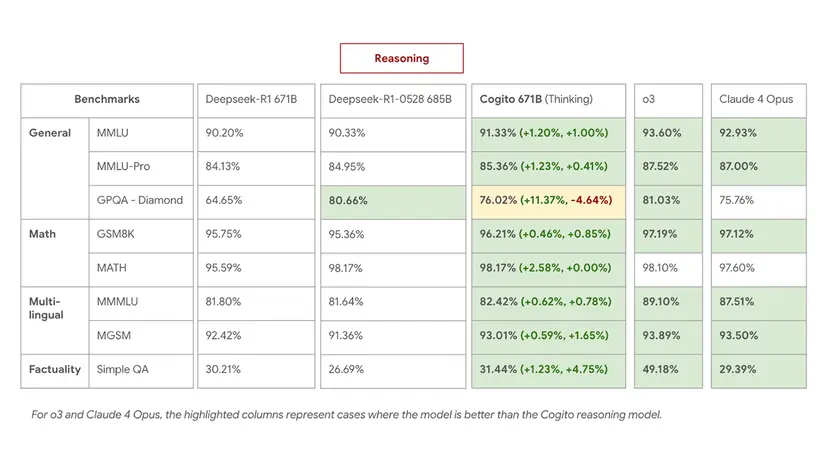
On MMLU, GSM8K, and MGSM, Cogito 671B MoE’s performance was roughly equivalent to top open models like Qwen1.5-72B and DeepSeek v3, and approached the performance level of closed models like Claude 4 Opus and o3.
Specifically:
Cogito 671B MoE (reasoning mode) matched DeepSeek R1 0528 in multilingual QA and general knowledge tasks, and surpassed it in strategy and logical deduction.
In non-reasoning mode, it outperformed DeepSeek v3 0324, indicating that the distilled intuition provided real performance benefits even without an extended reasoning path.
The model’s capacity to complete reasoning in fewer steps also had downstream effects: Reduced inference costs and faster response times for complex prompts.
Arora explains this as a distinction between searching for a path versus having a general idea of the destination.
“Since the Cogito models develop a better intuition of the trajectory to take during inference time, they have 60% shorter reasoning chains than Deepseek R1,” he wrote in a thread on X.
What kinds of tasks do Deep Cogito’s new models excel at when using their machine intuition?
Some of the most compelling examples from Cogito v2’s internal testing illustrate precisely how this manifests in practice.
In one math-heavy prompt, a user inquires whether a train traveling at 80 mph can reach a city 240 miles away in under 2.5 hours.
While many models simulate the calculation step-by-step and sometimes make unit conversion errors, Cogito 671B reflects internally, determines that 240 ÷ 80 = 3 hours, and accurately concludes that the train cannot arrive in time. It accomplishes this with only a brief internal reasoning trace — under 100 tokens — compared to the 200-plus used by DeepSeek R1 to reach the same conclusion.
In another scenario involving legal reasoning, a user questions whether a specific U.S. Supreme Court ruling would apply to a hypothetical case involving search and seizure. Cogito’s reasoning mode highlights a two-step logic: First determining whether the hypothetical aligns with the precedent, then explaining why it does or doesn’t. The model reaches a nuanced answer with clear justification — a type of interpretive reasoning that many LLMs still struggle with.
Other tasks demonstrate improvements in managing ambiguity. On a classic multi-hop question — “If Alice is Bob’s mother, and Bob is Charlie’s father, what is Alice to Charlie?” — models often get confused by pronouns. Cogito v2’s models correctly identify Alice as Charlie’s grandmother, even in slightly rephrased versions where other open models fail.
Efficiency at scale
Despite the considerable size of the new models, Deep Cogito claims to have trained all eight of its Cogito models — including smaller v1 checkpoints — for under $3.5 million in total, compared to the reported $100 million plus for some of OpenAI’s leading models.
This includes data generation, synthetic reinforcement, infrastructure, and more than 1,000 training experiments. Compared to the nine-figure budgets of other frontier models, it’s a fraction of the typical expenditure.
Arora attributes this frugality to the company’s core thesis: Smarter models require better priors, not more tokens.
By teaching the model to bypass redundant or misleading reasoning paths, Cogito v2 delivers stronger performance without increasing inference time.
This is a significant tradeoff for users running models on API infrastructure or edge devices where latency and cost are crucial factors.
What’s next for Deep Cogito and v2?
The release of Cogito v2 is not a final product but an iterative step. Arora describes the company’s roadmap as “hill climbing” — running models, learning from their reasoning traces, distilling them, and repeating the cycle. Over time, each model serves as a stepping stone for the next.
Every model released by Deep Cogito is open source, and the company states that this will remain true for future iterations.
Their work has already garnered attention and support from backers like Benchmark’s Eric Vishria and South Park Commons’ Aditya Agarwal.
Infrastructure partners include Hugging Face, Together AI, RunPod, Baseten, Meta’s Llama team, and Unsloth.
For developers, researchers, and enterprise teams, the models are now available. Developers can run them locally, compare modes, or fine-tune them for specific applications.
And for the broader open-source AI community, Cogito v2 offers more than just a new benchmark leader — it introduces a different approach to building intelligence. Not by thinking harder, but by learning how to think better.
Advertisement
Advertisement


Advertisement


