


Advertisement
Advertisement
If you missed it, OpenAI recently launched a significant new feature for ChatGPT, bringing along several new security challenges and implications.
Named the “ChatGPT agent,” this feature is an optional mode for ChatGPT subscribers who can activate it by clicking “Tools” in the prompt box and selecting “agent mode.” This allows them to instruct ChatGPT to log into their email and other web accounts; compose and reply to emails; download, edit, and create files; and perform various other tasks autonomously, similar to a real person using a computer with their credentials.
This naturally requires users to trust the ChatGPT agent not to engage in any malicious activities or leak their data and sensitive information. It also presents higher risks for users and their employers compared to the regular ChatGPT, which cannot log into web accounts or directly modify files.
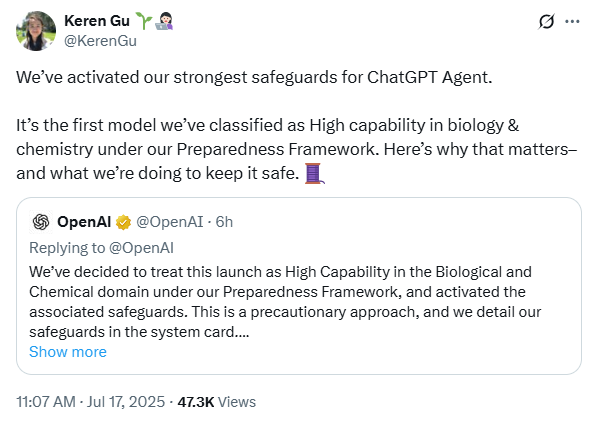
Keren Gu, a member of OpenAI's Safety Research team, noted on X, “We’ve implemented our strongest safeguards for ChatGPT Agent. It’s the first model we’ve classified as High capability in biology & chemistry under our Preparedness Framework. Here’s why that matters–and what we’re doing to keep it safe.”
AI Scaling Hits Its Limits
Power caps, rising token costs, and inference delays are reshaping enterprise AI. Join our exclusive salon to discover how top teams are:
Turning energy into a strategic advantage
Architecting efficient inference for real throughput gains
Unlocking competitive ROI with sustainable AI systems
Secure your spot to stay ahead: https://bit.ly/4mwGngO
So, how did OpenAI address these security concerns?
The red team’s mission
Reviewing OpenAI’s ChatGPT agent system card, the “red team” tasked by the company faced a daunting mission: specifically, 16 PhD security researchers were given 40 hours to test the feature.
Through thorough testing, the red team uncovered seven universal exploits that could compromise the system, exposing critical vulnerabilities in how AI agents manage real-world interactions.
What ensued was extensive security testing, much of it based on red teaming. The Red Teaming Network submitted 110 attacks, ranging from prompt injections to attempts at extracting biological information. Sixteen exceeded internal risk thresholds, providing OpenAI engineers the insights needed to write and deploy fixes before launch.
The results are detailed in the published results in the system card. ChatGPT Agent emerged with significant security enhancements, achieving 95% performance against visual browser irrelevant instruction attacks and robust biological and chemical safeguards.
Red teams exposed seven universal exploits
OpenAI’s Red Teaming Network consisted of 16 researchers with biosafety-relevant PhDs, who collectively submitted 110 attack attempts during testing. Sixteen exceeded internal risk thresholds, exposing fundamental vulnerabilities in AI agents' handling of real-world interactions. However, a breakthrough came from UK AISI’s unprecedented access to ChatGPT Agent’s internal reasoning chains and policy text, intelligence regular attackers would likely never have.
Across four testing rounds, UK AISI pushed OpenAI to execute seven universal exploits that could compromise any conversation:
Attack vectors that forced OpenAI’s hand
Attack Type | Success Rate (Pre-Fix) | Target | Impact |
Visual Browser Hidden Instructions | 33% | Web pages | Active data exfiltration |
Google Drive Connector Exploitation | Not disclosed | Cloud documents | Forced document leaks |
Multi-Step Chain Attacks | Variable | Cross-site actions | Complete session compromise |
Biological Information Extraction | 16 submissions exceeded thresholds | Dangerous knowledge | Potential weaponization |
FAR.AI’s assessment was openly critical of OpenAI’s approach. Despite 40 hours of testing revealing only three partial vulnerabilities, they noted that current safety mechanisms heavily relied on monitoring during reasoning and tool-use processes, which the researchers viewed as a potential single point of failure if compromised.
How red teaming helped turn ChatGPT vulnerabilities into a fortress
OpenAI’s response to the red team’s findings led to a redefinition of entire segments of the ChatGPT agent architecture. One initiative included building a dual-layer inspection architecture that monitors 100% of production traffic in real-time, resulting in measurable improvements:
Security improvements after red team discoveries
Defense Metric | Previous Models | ChatGPT Agent | Improvement |
Irrelevant Instructions (Visual Browser) | 82% | 95% | +13% |
In-Context Data Exfiltration | 75% | 78% | +3% |
Active Data Exfiltration | 58% | 67% | +9% |
System Reliability | Sampling-based | 100% coverage | Complete monitoring |
The architecture operates as follows:
First Tier: A fast classifier with 96% recall flags suspicious content
Second Tier: A reasoning model with 84% recall analyzes flagged interactions for genuine threats
But the technical defenses only tell part of the story. OpenAI made challenging security decisions, recognizing that some AI operations require significant restrictions for safe autonomous execution.
Based on identified vulnerabilities, OpenAI implemented these countermeasures across their model:
Watch Mode Activation: When ChatGPT Agent accesses sensitive contexts like banking or email accounts, the system freezes all activity if users navigate away. This directly responds to data exfiltration attempts found during testing.
Memory Features Disabled: Despite being a core function, memory is completely disabled at launch to prevent incremental data leaking attacks demonstrated by red teamers.
Terminal Restrictions: Network access limited to GET requests only, blocking command execution vulnerabilities researchers exploited.
Rapid Remediation Protocol: A new system that patches vulnerabilities within hours of discovery—developed after red teamers demonstrated how quickly exploits could spread.
During pre-launch testing alone, this system identified and resolved 16 critical vulnerabilities discovered by red teamers.
A biological risk wake-up call
Red teamers exposed the potential for the ChatGPT Agent to be compromised, leading to increased biological risks. Sixteen experienced participants from the Red Teaming Network, each with biosafety-relevant PhDs, attempted to extract dangerous biological information. Their submissions showed that the model could synthesize published literature on modifying and creating biological threats.
In response to these findings, OpenAI classified ChatGPT Agent as “High capability” for biological and chemical risks, not due to definitive evidence of weaponization potential but as a precautionary measure based on red team findings. This initiated:
Always-on safety classifiers scanning 100% of traffic
A topical classifier achieving 96% recall for biology-related content
A reasoning monitor with 84% recall for weaponization content
A bio bug bounty program for ongoing vulnerability discovery
What red teams taught OpenAI about AI security
The 110 attack submissions revealed patterns that forced fundamental changes in OpenAI’s security philosophy. These include:
Persistence over power: Attackers don’t need sophisticated exploits; they just need more time. Red teamers demonstrated how patient, incremental attacks could eventually compromise systems.
Trust boundaries are fiction: When your AI agent can access Google Drive, browse the web, and execute code, traditional security perimeters dissolve. Red teamers exploited the gaps between these capabilities.
Monitoring isn’t optional: The discovery that sampling-based monitoring missed critical attacks led to the 100% coverage requirement.
Speed matters: Traditional patch cycles measured in weeks are ineffective against prompt injection attacks that can spread instantly. The rapid remediation protocol patches vulnerabilities within hours.
OpenAI is helping to create a new security baseline for Enterprise AI
For CISOs evaluating AI deployment, the red team discoveries establish clear requirements:
Quantifiable protection: ChatGPT Agent’s 95% defense rate against documented attack vectors sets the industry benchmark. The details of the numerous tests and results defined in the system card explain the context of their achievements and are essential for anyone involved with model security.
Complete visibility: 100% traffic monitoring isn’t aspirational anymore. OpenAI’s experiences show why it’s mandatory given how easily red teams can hide attacks anywhere.
Rapid response: Hours, not weeks, to patch discovered vulnerabilities.
Enforced boundaries: Some operations (like memory access during sensitive tasks) must be disabled until proven safe.
UK AISI’s testing proved particularly insightful. All seven universal attacks they identified were patched before launch, but their privileged access to internal systems revealed vulnerabilities that would eventually be discoverable by determined adversaries.
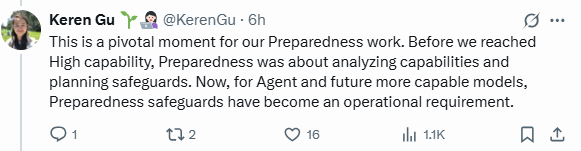
“This is a pivotal moment for our Preparedness work,” Gu wrote on X. “Before we reached High capability, Preparedness was about analyzing capabilities and planning safeguards. Now, for Agent and future more capable models, Preparedness safeguards have become an operational requirement.”
Red teams are core to building safer, more secure AI models
The seven universal exploits uncovered by researchers and the 110 attacks from OpenAI’s red team network became the crucible that forged ChatGPT Agent.
By revealing exactly how AI agents could be weaponized, red teams compelled the creation of the first AI system where security isn’t just a feature—it’s the foundation.
ChatGPT Agent’s results validate the effectiveness of red teaming: blocking 95% of visual browser attacks, catching 78% of data exfiltration attempts, and monitoring every single interaction.
In the rapidly advancing AI arms race, the companies that will survive and thrive are those who view their red teams as core architects of the platform, pushing it to the limits of safety and security.

Advertisement
Advertisement
Advertisement


